PrismML Unveils Tiny AI Models Poised to Revolutionize On-Device Intelligence
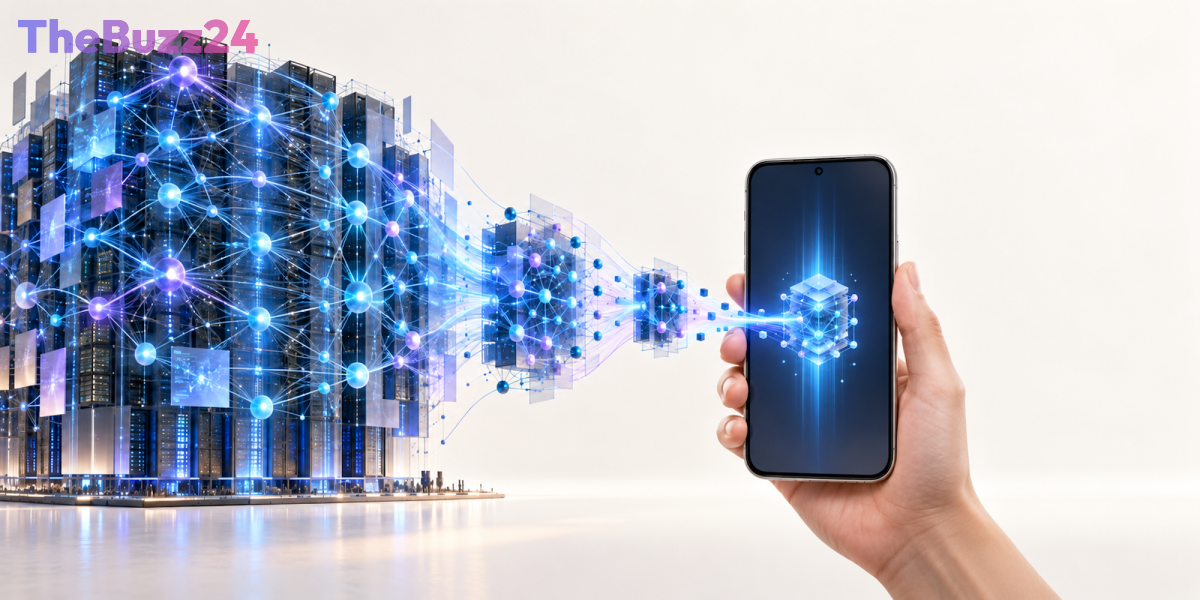
Artificial intelligence startup PrismML is making significant strides in developing highly capable large language models (LLMs) that defy conventional size limitations. The company’s core mission is to prove that powerful, reasoning-focused AI does not require massive computational resources, aiming instead to create models small enough to operate directly on personal computers and smartphones.
PrismML recently launched Bonsai 2 27B, an advanced iteration of its compressed LLM family. This new model successfully reduces the memory footprint of Alibaba’s widely adopted open-source Qwen3.8 27B model by a factor of nine to ten, bringing its size down to just 5.9 GB. This remarkable compression makes it feasible for the model to run on standard PCs and potentially high-end mobile devices, a significant leap towards democratizing advanced AI capabilities.
Founded by a team of researchers from Caltech, including AI compression expert and professor Babak Hassibi as CEO, PrismML is backed by notable investors such as Khosla Ventures and Cerberus Capital, along with support from Caltech itself. The startup’s innovative approach centers on a technique that simplifies the model’s ‘weights’ – the learned parameters that define its knowledge. By reducing these weights to a ternary system (+1, -1, or 0) instead of the standard 16-bit representation, PrismML drastically cuts down the model’s storage and memory requirements without a substantial loss in performance. The latest Bonsai 2 model achieves approximately 98% of the benchmark scores of its larger counterpart, a notable improvement from its predecessor which reached 95% performance parity.
Looking ahead, PrismML plans to apply its compression technology to even larger models, potentially in the hundreds of billions of parameters. CEO Babak Hassibi expressed optimism that compressing larger models will be more efficient, allowing for greater retention of intelligence. The vision, supported by advisors like Databricks co-founder Ion Stoica, is to enable advanced AI to run locally on user devices, offering enhanced privacy and accessibility by eliminating the need for cloud-based processing.
Key Takeaways
- PrismML has developed a technique to significantly compress large language models, making them suitable for on-device operation.
- The latest model, Bonsai 2 27B, achieves 98% of the performance of its larger counterpart while being 9-10x smaller.
- This innovation aims to bring advanced AI capabilities to personal computers and smartphones, enhancing privacy and accessibility.
Editor’s Analysis & Impact
PrismML’s breakthrough in LLM compression could fundamentally alter the AI landscape. By enabling powerful AI models to run locally on consumer devices, the company addresses critical concerns around data privacy, latency, and computational cost associated with cloud-based AI. This development is particularly significant for the mobile and PC markets, potentially spurring new applications and user experiences that were previously unfeasible. While challenges remain in achieving perfect performance parity, PrismML’s progress suggests a future where sophisticated AI is not confined to data centers but is readily available at the user’s fingertips, fostering wider adoption and innovation across industries.
Frequently Asked Questions
Q: What is PrismML's core innovation?
A: PrismML's core innovation is a compression technique that significantly reduces the size of large language models (LLMs) by simplifying their 'weights' to a ternary system (+1, -1, or 0). This allows powerful AI models to run on devices with limited resources like PCs and smartphones.
Q: How does PrismML's compression affect model performance?
A: PrismML claims its compression method results in minimal performance degradation. Their latest model, Bonsai 2 27B, achieves approximately 98% of the benchmark scores of the original, larger model, indicating a high level of performance retention.
Q: What are the potential benefits of running AI models on local devices?
A: Running AI models on local devices offers several benefits, including enhanced data privacy as sensitive information doesn't need to be sent to the cloud, reduced latency for faster responses, and lower operational costs since it utilizes existing device hardware.
AI Disclosure: This article is based on verified data and official reports. Our Team and AI have cross-referenced every financial detail with primary sources to ensure total accuracy.
More from this Category