Unsiloed AI Secures $7.5M to Bridge the Gap Between Complex Documents and AI Agents
Unsiloed AI, a startup focused on optimizing enterprise document processing, has successfully raised $7.5 million in a seed funding round led by Felicis. The investment, which also saw participation from Y Combinator, Orange Collective, and Uncorrelated Ventures, aims to accelerate the development of technology that makes complex business documents readable and actionable for AI agents. As companies increasingly rely on automation, the inability of AI to accurately interpret tables, charts, and intricate layouts remains a significant barrier to widespread adoption.
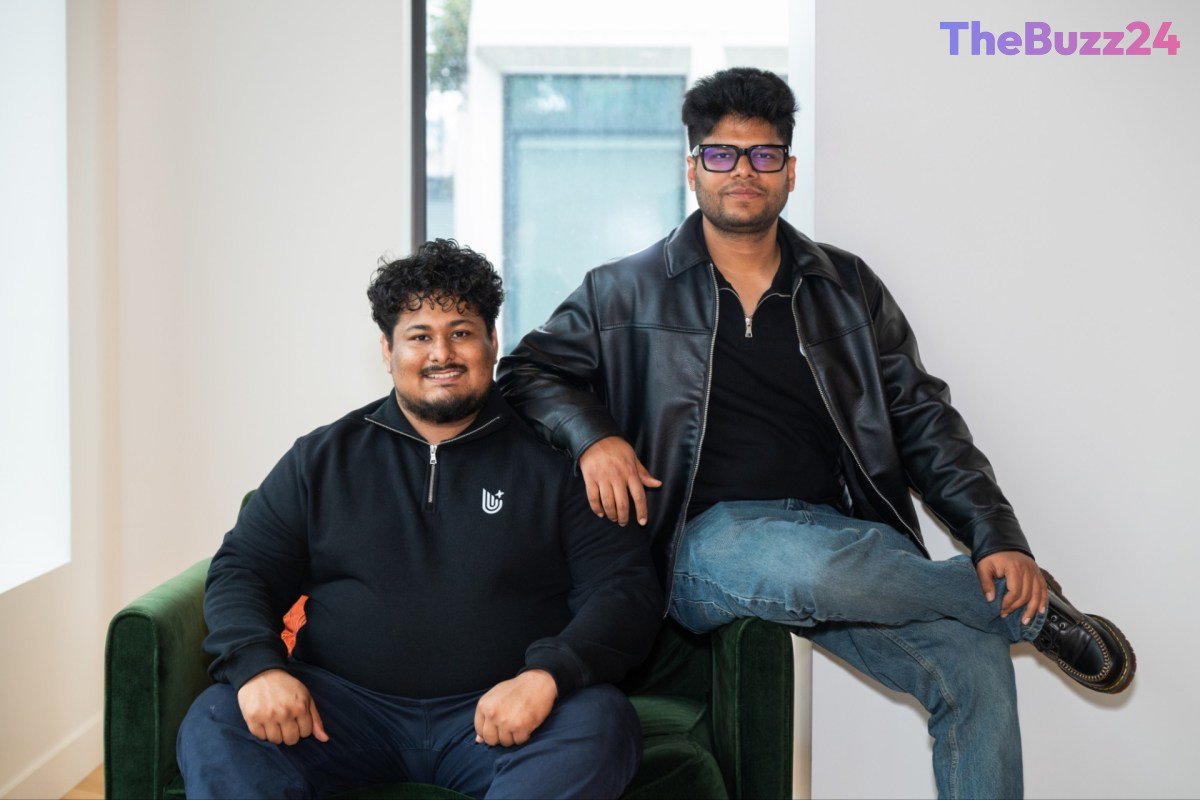
Founded by Aman Mishra and Adnan Abbas, Unsiloed AI addresses the inherent risks of AI hallucinations and data inaccuracies that can plague sectors like finance, law, and healthcare. The company’s proprietary technology utilizes a ‘dual-stream’ vision model that processes text and image data separately, combined with ‘heat map-based chunking’ to prioritize critical information. By converting unstructured documents into structured data, the platform allows AI agents to operate with higher precision while providing clear citations back to the original source material for verification.
Currently, the San Francisco-based startup is already seeing traction with clients in the legal and financial sectors, as well as with voice AI firms like Bolna AI. Despite entering a competitive landscape populated by major tech incumbents and specialized document-processing firms, Unsiloed claims superior performance metrics. Internal testing against industry benchmarks suggests the platform achieves high accuracy rates by intelligently allocating computing power to the most complex sections of a document, rather than processing every page uniformly.
With a current team of seven, Unsiloed plans to utilize the new capital to scale its engineering and research departments. The company intends to focus on expanding its sales operations and building proprietary datasets to further refine its document-parsing capabilities. As the demand for reliable, agent-ready data grows, Unsiloed is positioning itself as a critical infrastructure layer for the future of enterprise AI.
Key Takeaways
- Unsiloed AI raised $7.5 million in seed funding to improve how AI agents interpret complex enterprise documents.
- The startup uses a 'dual-stream' vision model and heat-map chunking to extract structured data from tables and charts with high accuracy.
- The company plans to use the funding to expand its research and engineering teams while scaling its presence in the finance, legal, and healthcare sectors.
Editor’s Analysis & Impact
The rise of AI agents in the enterprise sector is currently bottlenecked by the ‘unstructured data’ problem. While Large Language Models (LLMs) are powerful, they often struggle with the nuanced layouts of financial reports, legal contracts, and medical records, leading to costly errors. Unsiloed AI’s approach—prioritizing accuracy through specialized vision models—addresses a critical pain point for businesses that cannot afford the probabilistic nature of standard AI. The market for document intelligence is becoming increasingly crowded, but the ability to provide verifiable, structured data will likely be the primary differentiator for long-term success. If Unsiloed can maintain its performance lead over incumbents like Microsoft and Amazon, it could become an essential middleware provider for any organization looking to automate document-heavy workflows without sacrificing reliability.
Frequently Asked Questions
Q: What problem does Unsiloed AI solve for businesses?
A: Unsiloed AI converts complex, unstructured business documents—such as those containing tables, charts, and specific layouts—into structured data that AI agents can accurately interpret and use without hallucinating.
Q: How does Unsiloed AI differentiate itself from other document-processing tools?
A: The company uses a 'dual-stream' vision model that processes text and images separately, along with 'heat map-based chunking' to focus computing power on the most important parts of a document, resulting in higher accuracy and lower processing costs.
AI Disclosure: This article is based on verified data and official reports. Our Team and AI have cross-referenced every financial detail with primary sources to ensure total accuracy.
More from this Category